

Server Lifecycle
An inference server is one model running on one or more GPUs. This page covers its lifecycle; sizing, parallelism and the accelerations have pages of their own.
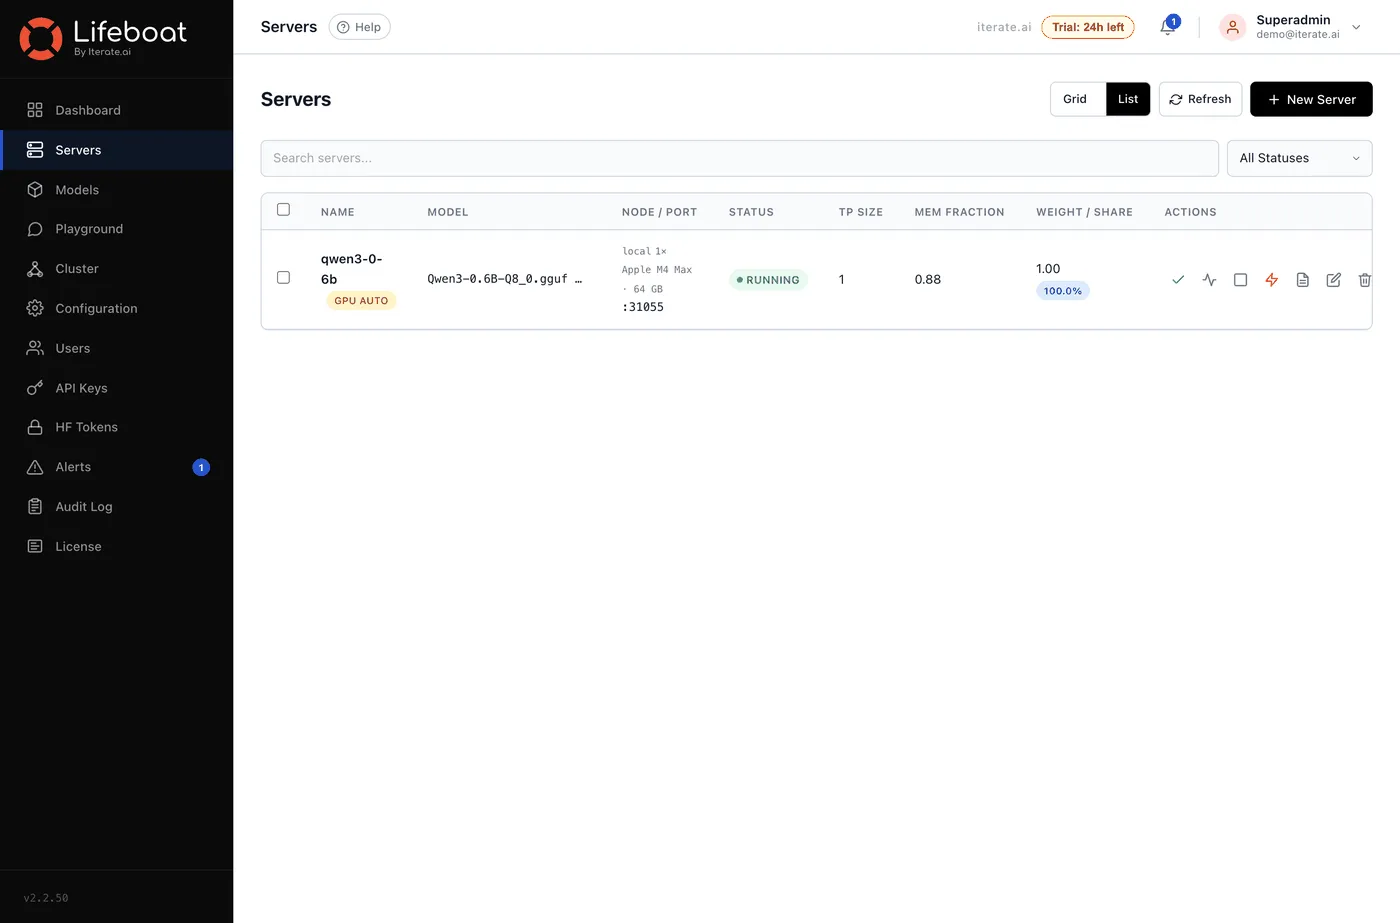
Create
Section titled “Create”Servers → Create Server. Model, name, port, and the settings you should leave on Auto — see Memory and sizing.
A server can be created before its weights exist. The path is resolved at start, so “register, create, download, start” is a valid order.
Statuses
Section titled “Statuses”| Status | Meaning | Action |
|---|---|---|
starting |
Loading weights, then capturing execution graphs. | Watch the log. Minutes is normal on a large model. |
running |
Healthy and in the routing pool. | — |
stopped |
Deliberately off. Not restarted on boot. | Start when wanted. |
error |
Failed to start, or crashed and exhausted retries. | Read the classified reason on the row. |
“Starting” is not “stuck”
Section titled ““Starting” is not “stuck””A server is only treated as stuck after both LIFEBOAT_STARTING_TIMEOUT_SEC (900s) has elapsed and LIFEBOAT_STARTING_STALL_SEC (300s) has passed with nothing written to its log.
That pairing is deliberate: a large mixture-of-experts model legitimately spends minutes capturing graph shapes and logs a line for each. Elapsed time alone cannot tell that apart from a hang; silence can. A log that cannot be read is not treated as stalled.
There is a hard ceiling (LIFEBOAT_STARTING_HARD_TIMEOUT_SEC, 3600s) that a live log cannot extend — “still logging” is only a proxy for “still working”, and a server wedged in a retry loop writes forever.
Boot auto-start
Section titled “Boot auto-start”After a host restart, Lifeboat restarts the servers that were up — running or starting.
stoppedis an explicit off and is left alone.errorrows are not relaunched locally. With several server rows per model, relaunching every row that ever failed once is how a GPU fills with servers nobody started.
A crash during a session is different and is recovered by the runtime restart loop, which is where a transient crash belongs.
Automatic restart
Section titled “Automatic restart”A server that crashes is restarted with a budget. Three failures disable retries, because retrying cannot succeed and only obscures the reason:
gpu_incompatible— the GPU is below the supported floor.insufficient_shared_memory— fixed at container creation.invalid_extra_args— a configuration error.
Repeated restarts raise a server_auto_restarted warning. Once after a transient is the system working; a pattern is a server that cannot stay up, and its log says why.
Reading logs
Section titled “Reading logs”Show Log tails the server’s own log. The panel survives a status change, so it can be left open across a start — which is when it is most useful.
The log is the authoritative account of a failure; the row’s message is a classification of it. When they seem to disagree, believe the log.
Previous run switches the panel to the log of the run before this one. A crashed server is usually restarted before anyone looks at it, and the restart used to overwrite the log — so the traceback explaining the crash was destroyed by the response to the crash. One previous run is now kept per server. Auto-refresh pauses while you are reading it, because a finished log does not change.
A server running on a remote node has no previous log — the node agent does not keep one — and the panel says so rather than quietly showing you the current one.
Stop terminates the process and removes the server from the routing pool. In-flight requests are not drained.
Lifeboat identifies its own processes by a tag it sets on them rather than by matching command lines, so stopping is precise even when several servers run the same model from the same path.
A stopped server releases its GPU memory, and does not hold any back. Another model can be started on the same GPU immediately, on Auto, without deleting anything.
If the memory does not come back — which happens when the recorded process id is stale, usually after the control plane itself restarted and orphaned the engine it had launched — the stop says so and names the processes still holding the card. Reap them from GPU Processes on that server. Without that, the first thing that would notice is your next start failing with a message about the GPU rather than about the stop.
Verify config
Section titled “Verify config”Verify config on a server row asks the running engine what it actually resolved, and compares that with what the server was configured with. Three verdicts matter differently:
| Verdict | Meaning |
|---|---|
| not reaching the engine | This build maps no engine flag for that key, so it was dropped before launch and the setting has no effect. Always worth acting on. |
| engine resolved something else | Often legitimate — a resolver, a clamp or a hardware gate may have had a good reason, and the engine’s value is the one in force. |
| applied | The engine reports the value that was asked for. |
Lifeboat also warns at the moment you save a server whose configuration contains a key this build cannot deliver, so you normally see this before the server is ever started.
Disaggregated halves
Section titled “Disaggregated halves”A server whose Disaggregation role is prefill or decode is half of a pair and is deliberately kept out of ordinary routing — see Prefill/decode disaggregation.
Several servers, one model
Section titled “Several servers, one model”Normal and supported — it is how you get replicas. Two things follow:
- Reserve is per model, not per row, so a spec-decode variant and a no-spec variant of the same weights are not charged twice.
- A row you created but have never started does reserve memory, because Lifeboat assumes you intend to start it. A row you stopped does not. So a duplicate you have never used costs headroom until you delete it, while one you stopped costs nothing. See Memory and sizing.
Sources and references
Section titled “Sources and references”- Every start failure: Troubleshooting server start
- Sizing: Memory and sizing
- Routing once it is up: Routing modes