

Playground
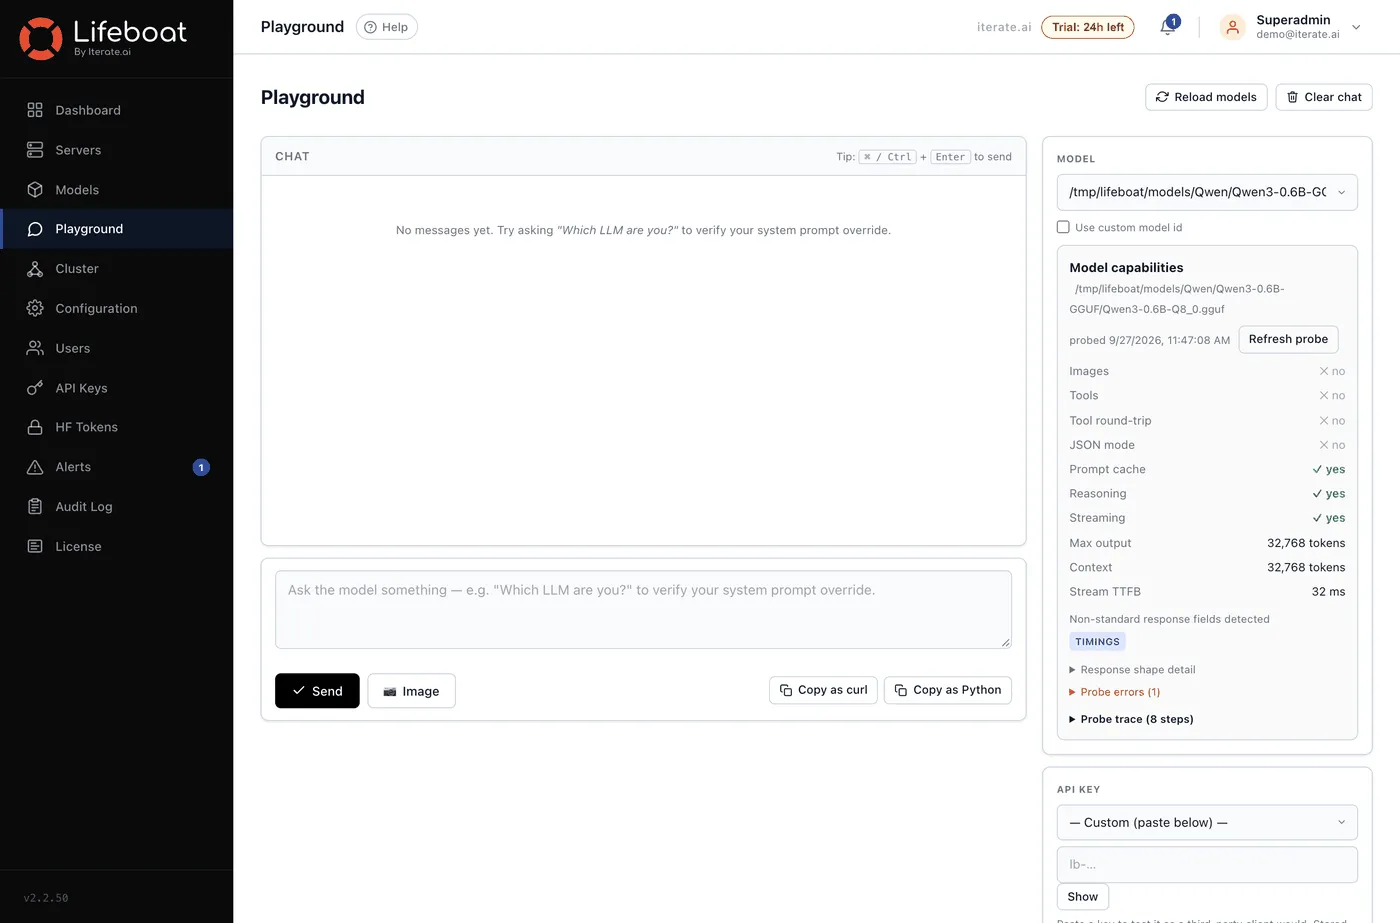
The Playground is a chat client built into the console. Its purpose is narrow and useful: confirm that a model you have just deployed actually works, and see how it behaves, without wiring up an API client or leaving the browser.
What can I do with it?
Section titled “What can I do with it?”Pick any running model and talk to it. Responses stream as they are generated, so time-to-first-token is visible rather than inferred. You can set a system prompt and adjust the usual sampling controls — temperature, top-p, maximum output tokens — per conversation.
The model list is the same one the API advertises, so a model that appears here is reachable by an application using the same name.
How does it relate to the API?
Section titled “How does it relate to the API?”It is an ordinary client of the same OpenAI-compatible endpoint your applications use, routed through the same load balancer with the same authentication. There is no privileged path: if the Playground can reach a model, so can an application, and if it cannot, neither can they. That is what makes it a useful first check.
Because the request goes through the load balancer, it also shows which backend served it — the per-request routing headers naming the chosen server, its pool, its weight, its in-flight count and any queue wait. On a multi-server deployment that turns “is traffic actually spread across my replicas” from a question into an observation.
What is it not?
Section titled “What is it not?”It is not a prompt-management or evaluation tool, and conversations are not persisted as a dataset. It holds the current conversation so a multi-turn exchange behaves like one; it is not a place to store prompts for reuse.
For a model that reports its own capabilities — real maximum output length, effective context window, JSON mode, tool calling, vision, reasoning traces — use the capability probe on the Models page rather than inferring them from a chat.
First checks when a model answers oddly
Section titled “First checks when a model answers oddly”- Thinking text appearing in the reply. Some models emit reasoning inline. Set the reasoning parser on the server so it is separated from the answer instead of printed in it.
- Tool-call markup appearing as visible text. The tool-call parser is unset or wrong for that model. Lifeboat detects and corrects this at server start for the formats it can prove from the model’s own chat template; anything else is a per-server setting.
- A long prompt rejected. The context window a model advertises is the smaller of what the model supports and what the deployment’s cache can hold. The Servers page reports both.
Sources and references
Section titled “Sources and references”- The same API, called directly: API and automation
- Routing and pool behaviour: Clusters and load balancing
- Capability probing: Model management